
Google Gemini and the Question Behind Multimodal AI: What Are You Actually Seeing?
Google Gemini is a useful case for understanding multimodal AI: what enters the system, what it transforms, what sources shape the answer and who remains responsible for the claim.
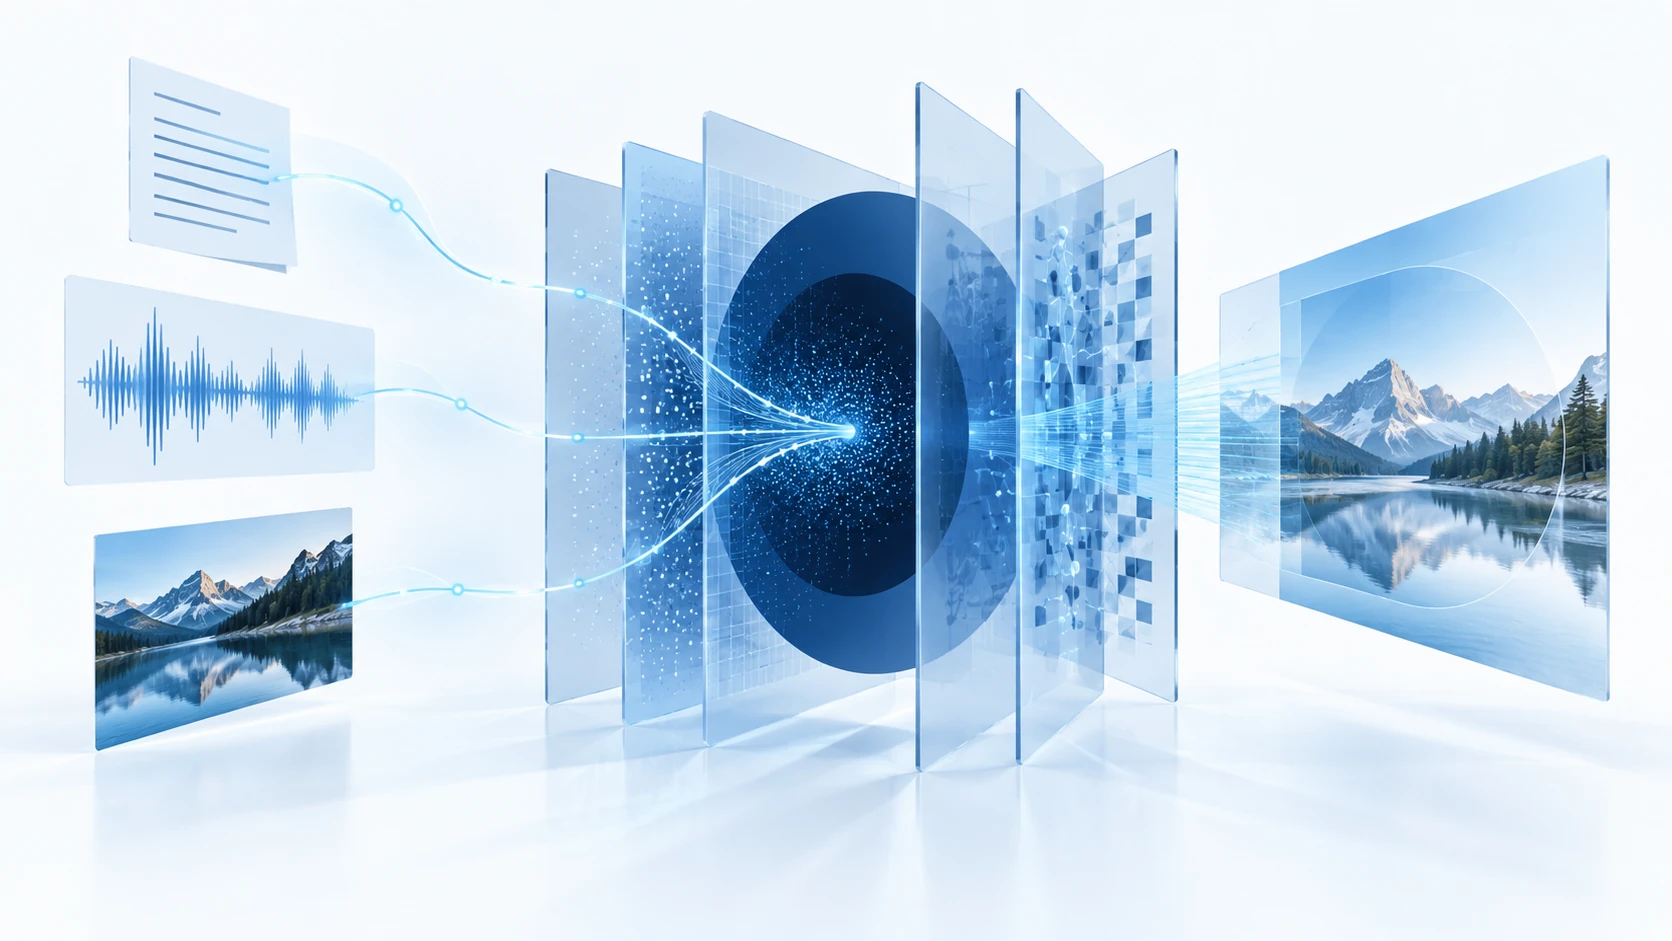
Google Gemini is often introduced as a race in scale: a newer model, more modalities, more products and a larger ambition for Google. That framing leaves out the question a reader needs before trusting a multimodal assistant: when text, images and audio enter the same system, what exactly am I being shown, and what remains outside the frame?
Gemini is a useful case because it sits at the meeting point of a conversational interface, a search company, a large account ecosystem and a model designed to work across different kinds of input. The product names and capabilities will change. The reader’s need for a clear account of the input, the source, the transformation and the responsibility will not.
This guide is not a permanent feature list. It gives you a way to understand what a multimodal assistant does, where its fluency can mislead you, and how to keep a person in charge of the claim.
What is Google Gemini?
Gemini is Google’s family of generative AI models and assistant experiences. A user may ask for an explanation, bring an image into a question, work with a document, or combine several forms of material in one interaction. The system generates a response from the patterns it has learned and the sources or tools made available in that context.
The name of a model does not tell you which version answered, what information it could access, whether a source was retrieved, or what transformations happened before the answer reached you. Those details are part of the meaning of the answer, not technical decoration.
What changes when one system handles several kinds of input?
An image becomes an interpretation
When you ask an assistant to describe a photograph, it is not handing you the scene untouched. It is selecting what it recognises, filling gaps with language and presenting a description through its learned categories. A confident description can still miss the person, place or event that matters most.
Audio becomes a chain of decisions
Speech must be detected, divided, transcribed and interpreted before a text answer is generated. A name, accent, hesitation or quiet background sound can disappear at any stage. Keep the original recording when the exact wording or sequence matters.
Documents become compressed context
A long document can be summarised quickly, but a summary changes the reader’s relationship with the evidence. Ask which passages support the conclusion, what was excluded and whether the system can distinguish the author’s claim from an example or quotation.
The interface makes the chain feel like one mind
A single chat box hides the movement between input, model, retrieval, policy and output. The result feels like a unified speaker even though several systems and decisions may be involved.
Why a fluent multimodal answer can still be wrong
More input does not automatically produce more understanding. A model can combine a photograph and a question into a plausible story without proving that the story happened. It can describe a document accurately in one paragraph and still omit the qualification that changes the decision.
Use multimodal assistance for exploration, comparison, transcription, drafting and questions. When the output affects health, money, rights, employment, education or a public record, return to the original material and make a human decision about the claim.
Five questions to ask before you rely on Gemini
1. What did the system actually receive?
List the prompt, files, images, audio, links and account context. Check whether the system saw the complete item or only a representation, excerpt or extracted text.
2. Where did the answer come from?
Separate what was read from your material, what was retrieved from elsewhere and what was generated from a learned pattern. Open the source and verify the sentence that matters.
3. What changed between the input and the output?
Record transcription, cropping, OCR, summarisation, translation, classification and other transformations. Each step can remove context while making the final answer easier to read.
4. Which defaults are shaping the result?
Google’s model, search ranking, account settings, safety rules and connected services all influence what becomes visible. Ask what the system would have done without your correction and what it cannot show you.
5. Who owns the final claim?
Assign a person to approve the statement before it is published or used. A multimodal assistant can speed up inspection; it cannot accept responsibility for a decision made from its output.
Google’s ecosystem is part of the answer
Gemini does not operate in an empty room. It can sit beside search, documents, devices, accounts and other services. That integration can make useful context easier to reach, but it can also make the boundary between your material, the platform’s data and the model’s interpretation harder to see.
Convenience should not require surrendering the record of how a decision was made. Keep the original input, the retrieved sources, the generated answer and the human edits together. If the service changes a model or a permission, your account of the decision should remain portable.
The solution is visible context and human control
A responsible multimodal system should show what it received, what it used, what it transformed and where uncertainty remains. People should be able to correct an answer, preserve the source and leave with their work. The assistant should make the path from evidence to claim easier to inspect, not replace that path with a polished sentence.
This connects to the wider argument behind Lu Heng’s work. His guide to generative AI explains why an instruction is not understanding. His Note on reality layers and symbolic power asks readers to separate what exists from the labels and narratives placed over it. Multimodal systems make that separation more urgent because they can attach a convincing narrative to more kinds of material.
Why the distinction matters now
Images, recordings and documents are moving into AI interfaces faster than most people can learn to inspect the transformations. If a fluent answer becomes the only version that travels, the system operator gains influence over which evidence survives, which context disappears and which interpretation feels obvious.
The important question is not whether Gemini wins a feature comparison. It is whether people can use an integrated AI system while keeping the right to see the source, understand the transformation, challenge the output and make the final decision themselves.
Start with one file and one checkable claim
Give the assistant one document, image or recording and ask a narrow question. Keep the original beside the response. Mark what is directly present, what is inferred and what needs another source. If the tool helps you see more clearly, keep it in the process. If it only makes an unsupported story easier to repeat, stop before the story becomes the record.